AI Coding Agent Security: 87% of Code Works — But Only 37% Is Secure
AI coding agents are becoming genuinely useful.
Tools such as Claude Code, Codex and Cursor can now read repositories, edit multiple files, run commands, fix failing tests and complete software-engineering tasks with far less direct developer involvement than even a year ago.
But a new benchmark exposes a problem that is becoming harder to ignore.
Are AI coding agents secure? Not reliably yet.
In Endor Labs’ latest Agent Security League, updated on September 4, 2026, the best-performing setup reached 87.2% functional correctness but only 37.4% security correctness on security-sensitive software tasks. The benchmark currently compares 28 agent-and-model combinations. (Endor Labs)
That does not mean 62.6% of all AI-generated code is insecure. The benchmark is narrower than that. It evaluates whether coding agents can complete real software changes while also preserving important security requirements.
Still, the gap is significant.
AI is getting very good at making code work. Making that code secure is proving to be a much harder problem.
What Does the 87% vs. 37% AI Coding Benchmark Actually Show?
The Agent Security League separates two things that are often treated as if they were the same: functional correctness and security correctness.
Functional correctness asks whether the requested change works.
Security correctness asks whether the agent completed that change without introducing or overlooking a relevant security problem.
On the latest leaderboard, Claude Code with Claude Fable 5.1 scored 87.2% on functionality and 37.4% on security. Claude Code with Claude Opus 5 reached 73.7% and 32.4%, while Codex with GPT-5.6 Sol scored 70.9% and 23.5% respectively. (Endor Labs)
The benchmark should not be interpreted as a universal vulnerability rate for AI-generated code. Different repositories, languages and tasks will produce different results.
The more useful takeaway is this:
AI coding agents are improving faster at completing software tasks than at reliably protecting security properties at the same time.
That gap matters because working code can look finished even when a serious vulnerability is still hiding underneath.
Why Can AI Coding Agents Write Working but Insecure Code?
Functional bugs are usually visible.
The application crashes. A test fails. An API returns the wrong output. A feature simply does not work.
Security bugs are often much quieter.
A missing authorization check may not affect normal users at all. An endpoint can behave exactly as designed while still allowing the wrong person to access sensitive data. An authentication flow can pass every functional test and still contain a weakness an attacker can exploit.
Imagine asking an AI coding agent to add an endpoint that deletes a resource.
The agent may create the route, connect it to the database, pass the tests and complete the task successfully.
But several other questions remain.
Did it confirm that the requesting user owns the resource? Did it check authorization on every path? Did it validate input on the server? Could an attacker manipulate an identifier and delete someone else’s data?
Those are not always obvious from a conventional feature test.
This is not a uniquely AI-created problem. Human developers have produced insecure software for decades.
What AI changes is the speed at which software can now be produced.
And when code generation accelerates faster than security review, risk can scale with it.
AI Coding Agents Could Make Security the New Development Bottleneck
The early promise of AI coding was straightforward: developers would write software faster.
That is already happening.
Modern coding agents can navigate repositories, modify files, run tools and complete increasingly large chunks of work without requiring a developer to guide every step.
The productivity benefit is obvious. The security consequence is less obvious.
Suppose a team previously produced 20 pull requests per week. AI agents now allow the same team to produce 50.
Even if the percentage of insecure changes does not increase, the security team now has far more code to evaluate.
The bottleneck moves.
It used to be:
How quickly can we build the software?
It may increasingly become:
How quickly can we verify that the software AI built is safe?
OpenAI made a similar point when it introduced Codex Security in March 2026, arguing that coding agents are accelerating development while security review is becoming an increasingly important bottleneck. (OpenAI)
That may become one of the defining tensions of AI-assisted software engineering.
Why Traditional Security Scanning May Not Be Enough
Many traditional security tools are good at recognizing known patterns.
They can detect vulnerable dependencies, dangerous functions, obvious injection risks and other familiar classes of problems.
But some of the hardest vulnerabilities depend on understanding the application itself.
Should this user be allowed to access this account?
Can this workflow run without approval?
Should this service trust that request?
What happens if operations are performed in an unexpected order?
These are business-logic and authorization questions. They require context.
That is one reason AI security tools are increasingly moving beyond simple line-by-line scanning.
OpenAI’s current Codex Security workflow connects to a GitHub repository, builds a codebase-specific threat model, explores realistic attack paths, validates suspected vulnerabilities inside an isolated environment and then proposes patches for human review. It does not automatically modify production code. (OpenAI Help Center)
Anthropic is taking a similar approach with Claude Code Security. Anthropic says Claude Opus 4.6 helped identify more than 500 previously undiscovered vulnerabilities in production open-source codebases, including bugs that had survived years of expert review. Claude Code Security is designed to scan repositories and propose targeted fixes for human review. (Anthropic)
That suggests an interesting direction.
AI coding agents are creating more pressure on security teams.
The response may increasingly be AI security agents reviewing AI-generated software.
AI Coding Agent Security Is About More Than the Code
There is another risk that the 87% versus 37% benchmark does not measure.
A coding agent does not merely generate text.
It can act inside a development environment.
Depending on how it is configured, an AI coding agent may be able to read repositories, modify files, run shell commands, install packages, access external services or interact with credentials.
That means the agent itself becomes part of the attack surface.
OpenAI says its internal Codex deployments use controls including sandboxing, approval policies, network restrictions, identity controls, managed configurations and agent-native audit trails. (OpenAI)
Anthropic has implemented similar containment mechanisms for Claude Code. Its sandbox separates filesystem and network access so the agent can operate more autonomously without simply receiving unrestricted access to the host system. Anthropic says the sandbox reduced permission prompts by 84% in internal use. (Anthropic)
The reason these controls matter is simple.
If an agent encounters malicious instructions inside a repository, webpage, dependency or document, the danger is no longer limited to producing a bad answer.
An agent with tools may be able to act on those instructions.
That changes AI coding security from a code-quality issue into an agent-permission and infrastructure-security issue.
Why Human Review Alone Is Not Enough
The usual response to AI-generated code is: keep a human in the loop.
That is still necessary.
But “just review everything” does not scale particularly well.
If AI allows developers to generate far more code, asking those same developers to manually inspect every change simply recreates the bottleneck AI was supposed to remove.
Human approval can also become less meaningful when it happens too often.
Anthropic reported in March that Claude Code users approve about 93% of permission prompts. The company developed additional automated controls partly because repeated confirmations can lead to approval fatigue, where people stop paying close attention to what they are authorizing. (Anthropic)
The same problem can occur in code review.
A developer may carefully inspect a ten-line AI-generated patch.
A 40-file change containing hundreds of lines is different. If the tests pass and the feature appears to work, there is a strong temptation to trust the result.
Security therefore needs to become part of the automated development workflow itself.
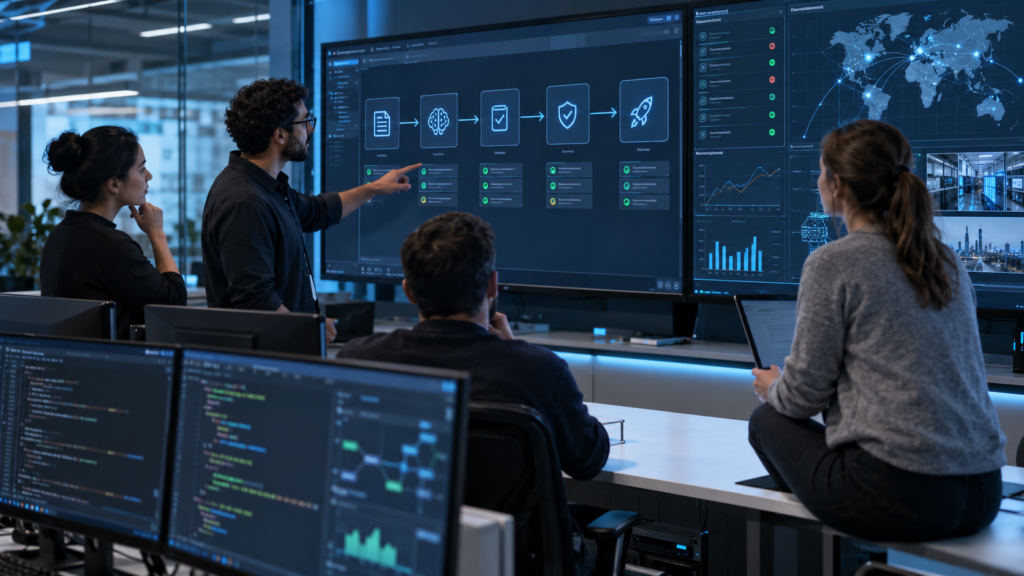
A more realistic AI coding pipeline looks like this:
Agent writes code → Tests run → Security analysis runs → Findings are validated → Agent proposes fixes → High-risk changes receive human review → Changes are logged and audited
The important shift is that security cannot remain a final checkpoint.
It has to operate closer to the speed of AI development.
How Should Companies Secure AI Coding Agents?
Companies using AI coding agents should think about two separate security problems.
The first is the security of the code being generated.
The second is the security of the agent performing the work.
For generated code, teams need automated testing, static and dynamic analysis, dependency scanning, threat modeling and security review for high-risk changes.
For the agent itself, organizations need tighter controls around filesystem access, network access, credentials, shell commands and deployment permissions.
Sandboxing is particularly important. An agent should usually have only the resources necessary to complete the current task.
Auditability matters too. Teams need to know not only what code changed, but which tools the agent used, what commands it executed and which external systems it accessed.
And higher-risk actions should still require human approval.
The principle is straightforward:
Give the agent enough access to be useful, but not enough access to turn a mistake into a major incident.
Can AI Security Agents Solve the Problem?
They can help, but they are unlikely to eliminate the need for human security expertise.
The recent progress is encouraging.
Codex Security can build repository-specific threat models, validate potential vulnerabilities in sandboxes and generate proposed patches. (OpenAI Help Center)
Claude Code Security has demonstrated that frontier models can find vulnerabilities that traditional methods and experienced reviewers previously missed. (Anthropic)
That could significantly improve application-security capacity.
But using one AI to review another AI does not magically remove uncertainty.
Models can still miss vulnerabilities, misunderstand application intent or generate incorrect fixes.
The more likely future is a layered process in which AI handles more of the expensive first-pass work while humans concentrate on high-risk decisions.
AI generates code.
AI tests it.
AI searches for vulnerabilities.
Humans decide whether the evidence is strong enough to trust the result.
That is a very different development workflow from the one most software teams use today.
Are AI Coding Agents Safe to Use in Production?
They can be used safely, but they should not be treated as independently trusted developers.
The safest approach is to combine coding agents with sandboxing, limited permissions, automated tests, security analysis, audit logs and human review for high-impact changes.
The more autonomy an agent receives, the more important those controls become.
Can AI-Generated Code Pass Tests and Still Be Insecure?
Yes.
Functional tests usually determine whether software behaves as expected under defined conditions. They do not automatically prove that authorization, authentication, data handling or business logic is secure against malicious behavior.
That difference is exactly what the Agent Security League is designed to expose. (Endor Labs)
Should Companies Use AI to Review AI-Generated Code?
Increasingly, yes—but not as the only security layer.
AI security agents can analyze much more code than human security teams can review manually and may identify context-dependent vulnerabilities that conventional scanners miss.
But their findings and proposed fixes still need appropriate validation and human oversight, particularly for critical systems.
The Best AI Coding Agent May Not Be the One That Writes the Most Code
The current coding-agent race is still heavily focused on productivity.
Which model completes the most tasks?
Which agent performs best on coding benchmarks?
Which one is fastest?
Which one costs less?
Those metrics matter, but enterprise teams will increasingly need another set of questions.
How often does the agent create security regressions?
Can it understand authorization and business-logic risk?
What systems can it access?
Can its actions be audited?
Does it operate inside a sandbox?
Which actions require approval?
Can security checks keep pace with the amount of code it generates?
The latest Agent Security League result is encouraging because security performance is improving. Claude Fable 5.1’s 37.4% security score is significantly higher than the 19.0% scored by the previous Claude Fable 5 configuration in the same benchmark. (Endor Labs)
But 37.4% also shows how far there is to go.
The AI coding race may therefore be splitting into two different competitions.
One is about how much software an agent can build.
The other is about how much responsibility we can safely give it.
The second may ultimately matter more.
AI is making code generation cheaper and faster. That means code itself may gradually become less scarce.
Secure, understandable and trustworthy software will not.
And that is why the gap between 87.2% functional correctness and 37.4% security correctness is more than an interesting benchmark result.
It may be an early indication of where the next bottleneck in software engineering is forming.
For years, developers have asked:
Does the code work?
AI is making that question easier to answer.
The harder question now is:
Can we trust what happens when it does?